An API rate limit is a cap on how many requests a client can send to an API in a set period, such as 60 per minute or 10,000 per month. When you go over it, the server rejects your calls, usually with an HTTP 429 status, until the window resets. This guide explains how limits are counted, how to read the signals an API sends back, and how to build code that stays under the ceiling.
TL;DR
- A rate limit caps requests per time window. Providers use it to prevent overload, keep usage fair, and control cost.
- Limits can be tied to an API key, a user, an app, or an IP address, and they come in several shapes: per second, per day, per month, or by tokens or points.
- HTTP 429 means "slow down." Read the
Retry-Afterheader first. If it is missing, use exponential backoff with random jitter and a retry cap. - Most limit trouble comes from avoidable habits: tight polling loops, bursts, and fetching a fresh auth token on every call.
- If your traffic is legitimate and the provider's limits apply per IP, spreading requests across connections can help. Always stay within the provider's terms.
Table of Contents
- What an API rate limit is
- Why providers set limits
- The kinds of limits you will meet
- What happens when you hit the limit
- How to fix a rate limit exceeded error
- Staying under the limit as traffic grows
- Limits on AI, social, and messaging APIs
- Our perspective
- Where a VPN fits in your workflow
- Try Lockshield for your travel and API work
- FAQ
- Sources
What an API rate limit is
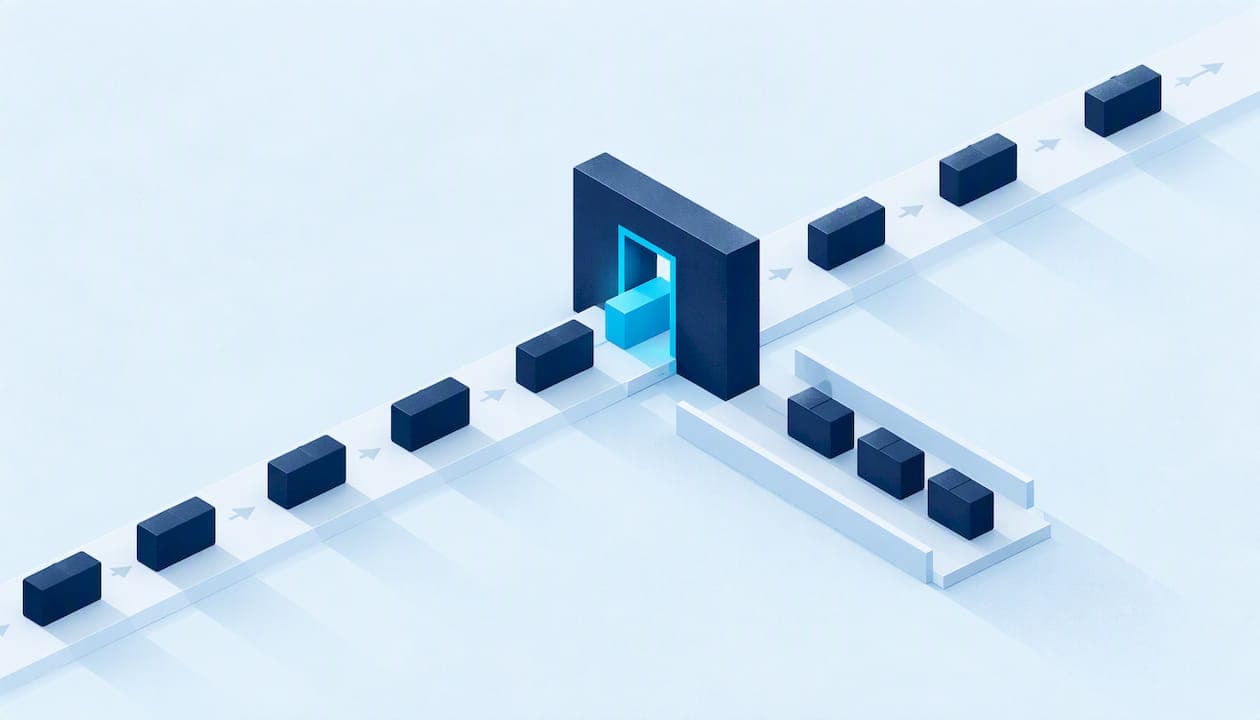
Think of a rate limit as a turnstile. The API lets a client through at a certain pace, and anything faster waits outside. Microsoft describes it as a cap on the speed and volume of API calls, commonly written as requests per period of time. An ACM paper on rate limit adoption defines it more formally: a maximum number of requests from a specific client during a defined interval, with windows measured in minutes, hours, days, or months.
The phrase "request limits" means the same thing. You will also see "throttling," which usually describes the server slowing or rejecting traffic once the limit is reached.
Two details matter from the start:
- The limit belongs to someone. The provider has to know who is calling. API Patterns notes that this needs a client identifier such as an API key, an IP address, or another authentication mechanism. MDN adds that limits may be based on IP, user, application, server, or resource.
- The window is part of the rule. "1,000 requests" means nothing until you know whether that is per minute, per day, or per month.
Why providers set limits
Limits are not only a way to make money from access, though pricing tiers often use them. Microsoft lists five reasons cloud API producers impose limits: preventing overload, fair usage, security, cost management, and consistent quality of service. The ACM authors frame rate limiting as both a reliability and a security control, since it prevents backend exhaustion and denial-of-service effects while sharing resources fairly.
For you as a developer, this means a limit is rarely arbitrary. It protects the service you depend on, and it protects your own app from a neighbor's runaway script.
The kinds of limits you will meet
The ACM paper describes limits that count requests over minutes, hours, days, or months, that are either static or adapt dynamically to client behavior and system capacity, and that use request-, time-, or point-based metrics. In practice, they fall into these groups.
| Type | What it controls | Typical use |
|---|---|---|
| Rate limit (burst) | Calls per second or minute | Protects against short, intense spikes |
| Quota | Total calls over a longer period, such as a month | Plan tiers and billing |
| Per-user limit | Calls attributed to one end user | Fairness inside a shared app |
| Per-key or per-project limit | Calls across an account or project | Capacity planning |
| Token or point limit | Weighted cost per call | Expensive operations count for more |
| Dynamic limit | Changes with load or behavior | Abuse and overload protection |
Microsoft Azure draws a clear line between the first two: rate limits protect against short bursts, while quotas control total calls over a longer period such as a month. Its tier example is a Basic subscription with 10,000 calls per month against a Premium subscription with 100,000,000. Those are illustrations, not universal numbers.
Real numbers, so you can calibrate
Exact figures differ wildly. API Patterns cites an unauthenticated GitHub REST API allowance of 60 requests per hour and an authenticated one of 5,000 per hour. That is an 80-fold jump just from identifying yourself.

Google Cloud lets you cap requests per second per user and requests per day, and it permits short-term spikes on the per-user per-second limit, so sustained average traffic should guide your configuration. One gotcha: Google identifies users for short-term capping with the quotaUser parameter. Without it, server-side calls are attributed to the calling server machines, so all your users share one bucket.
Some providers do not publish numbers at all. PayPal says exact limits are not published because they vary by API, environment, and circumstances. In that case, you learn your ceiling from the response headers and from testing.
What happens when you hit the limit
The standard answer is HTTP 429 Too Many Requests. MDN explains that it means the client sent too many requests in a given time, and that a Retry-After header may say how long to wait. The National Bank of Belgium's API design guide also recommends 429 for this case, citing RFC 6585.
The AWS Well-Architected framework describes the mechanism simply: requests below the throttling rate are processed, and requests above the limit are rejected with a throttling message, so clients can retry later.
Some services separate two situations. Microsoft's Xandr API documents 429 for user-level limits and 503 Service Unavailable when the service itself is overwhelmed. A rate-limiting 503 carries an x-ratelimit-code header. Handle both.
Reading the headers
Good APIs tell you where you stand before you hit the wall. The Belgian design guide recommends three headers: X-RateLimit-Limit for the allowance, X-RateLimit-Remaining for calls left, and X-RateLimit-Reset for the remaining window in UTC epoch seconds. Naming varies by provider. OpenAI, for example, documents x-ratelimit-limit-requests, x-ratelimit-remaining-requests, and x-ratelimit-reset-requests, plus matching token fields.
Log these on every response. A dashboard of "remaining" over time shows you exactly which code path burns the budget.
How to fix a rate limit exceeded error
Start by reading the status and the error code. Not every failure that looks like a limit is one, and the right fix depends on which it is.
- Check the status and code. OpenAI's guidance separates temporary rate-limit or overload errors from quota or billing errors. Retrying a quota error just wastes calls, because waiting does not add credit.
- Honor
Retry-After. Xandr tells clients to inspect the header and sleep for that many seconds before retrying a 429 or a rate-limiting 503. OpenAI treats it as a minimum wait and suggests adding a small random delay. - No header? Back off exponentially with jitter. Double the delay after each failure and add randomness so many clients do not retry in lockstep. The same OpenAI guide recommends capping the number of retries and lowering your request rate.
- Do not hammer. Microsoft warns that apps which ignore 429s may crash, retry so fast that throttling persists, or silently drop data.
A minimal retry loop in plain terms: send the request; if the status is 429 or 503, wait for Retry-After seconds or, failing that, min(cap, base * 2^attempt) + random(0, 1) seconds; try again up to five times; then surface the error to your queue or user instead of looping forever.
Habits that cause limits in the first place
PayPal lists the usual culprits: excessive polling, traffic spikes, repeatedly obtaining OAuth tokens instead of reusing them, and suspicious patterns. Its fix for polling is to use webhooks, so the provider calls you when something changes.
A quick audit usually finds savings:
- Cache responses that do not change every second.
- Reuse access tokens until they expire.
- Batch operations where the API supports it.
- Replace polling loops with webhooks or longer intervals.
- Pass a user identifier where the API supports one, so users do not share a single bucket.
Staying under the limit as traffic grows
Small apps rarely notice limits. Trouble starts when a launch, a cron job, or a batch import multiplies requests. Several patterns help.
Buffer with a queue. AWS recommends using queues or streams to buffer asynchronous work and setting a concurrency limit on queue consumers. Your workers then drain the queue at a pace the API accepts, instead of firing everything at once.
Throttle yourself first. The same AWS guidance suggests a token-bucket algorithm: tokens represent requests, refill at a configured rate, and each request consumes one. Run that on the client side, set slightly below the provider's limit, and you rarely see a 429.
Test your limits. AWS advises configuring tested throttle limits at the account or region, API or stage, and API-key or usage-plan levels. The same idea applies when you consume an API: find your real ceiling in a staging environment, not in production.
Spread by identity where allowed. Some providers meter by IP, and others by key or user. Know which one you face before choosing a strategy. Rotating IPs does nothing against a per-key limit, and it can look like abuse.

Limits on AI, social, and messaging APIs
Newer APIs often meter more than request counts. OpenAI documents request-based and consumption-based metrics, including RPM, RPD, TPM, TPD, IPM, and audio minutes per minute, and whichever limit you reach first is the one that constrains you. Limits can also be scoped at organization and project level, can vary by model, and may be shared across model families. A job with few but very large requests can hit a token limit long before a request limit.
The lesson holds for social platforms, messaging services, and video APIs too: read the provider's documentation for the unit being counted, the scope (app, user, or IP), and the window. Then size your queue and retry logic to match.
Our perspective
Most rate-limit advice stops at "add a backoff." That is necessary, but in our experience developers hit the next wall right after: the network their code runs on.
Teams working from hotels, airports, and shared offices often share one public IP address with dozens of strangers. When a provider meters by IP, your quiet script can inherit someone else's traffic and get throttled for it. Travelers also find that some services behave differently or become unreachable depending on where they connect from, which breaks the tools they need to get work done.
We built Lockshield VPN around that reality. It encrypts traffic on untrusted networks, deploys quickly, and works on iOS, Android, macOS, Windows, Linux, and TV, with native Linux support aimed at business and professional integrations. For workloads where the provider's limits apply per IP, parallel requests through our service can spread legitimate traffic across connections instead of funneling it through one address.
We are also clear about what a VPN does not do. It does not replace good client design, and it does not lift a limit tied to your API key or account. Use queues, caching, and backoff first, then use the network layer to remove avoidable bottlenecks, always within the provider's terms.
the author
Where a VPN fits in your workflow
A VPN is not a fix for a 429, but it solves two network problems that sit next to rate limits.
- Shared or untrusted networks. Hotel and airport Wi-Fi expose traffic and put many users behind the same address. Encryption protects your API keys and tokens in transit, and a dedicated connection avoids inheriting a crowded IP's reputation.
- Access restrictions while traveling. Some tools, social platforms, messaging apps, and AI services are limited in certain regions. A VPN lets you reach the services your team uses from wherever you work.
For developers, the practical checklist is short: confirm whether the limit is per IP, per key, or per user; keep your own throttle below the published ceiling; and only distribute traffic across connections when the provider's terms allow it.
Try Lockshield for your travel and API work
If your work depends on stable, secure connectivity on the road, or you run parallel API requests where limits apply per IP, we built Lockshield VPN for that. You buy a pre-paid access period of 1, 3, 6, or 12 months in a one-time payment, with no subscription and no auto-renewal.

Setup is quick, it works with native and third-party VPN clients, and it covers Linux as well as mobile, desktop, and TV platforms. See the options on the Lockshield VPN site.
FAQ
What is an API rate limit in simple terms?
It is a limit on how many requests you can send to an API in a given time, such as 60 per minute or 10,000 per month. Providers set it to prevent overload, keep usage fair, and manage cost. Go over it and the API typically answers with HTTP 429 until the window resets.
What does "rate limited" mean?
It means the server has temporarily refused your requests because you sent too many too quickly. The refusal is usually a 429 status, sometimes with a Retry-After header telling you how long to wait. It is normally temporary, and well-behaved clients wait and retry rather than resending instantly.
How do I fix an API rate limit exceeded error?
First confirm it is a rate limit and not a quota or billing problem. Then wait for the time in Retry-After, or use exponential backoff with jitter and a retry cap. To prevent repeats, cache responses, reuse tokens, batch calls, use webhooks instead of polling, and queue work so you send at a steady pace.
Do I have to pay for an API?
Not always. Many providers offer free tiers with low limits and sell higher quotas on paid plans. Azure's example shows a Basic plan at 10,000 calls per month against a Premium plan at 100,000,000. Check each provider's pricing and limits page, since figures differ by provider and plan.
What is the difference between a rate limit and a quota?
A rate limit controls how fast you can call, protecting against bursts. A quota controls how many calls you can make over a longer period, such as a month. You can hit one without the other, so track both.
Sources
- 429 Too Many Requests, MDN Web Docs
- What Is Rate Limiting? Dev Proxy, Microsoft Learn
- API Rate Limit Adoption: A pattern collection, ACM
- Advanced Request Throttling with Azure API Management
- Capping API usage, Google API Console Help
- Rate limiting with PayPal REST APIs
- Rate Limit pattern, API Patterns
- Rate limiting, National Bank of Belgium REST API Design Guide
- REL05-BP02 Throttle requests, AWS Well-Architected
- API Usage Constraints, Microsoft Xandr
- Rate limits, OpenAI